How we plan, build, and deliver digital projects
Delivery is where good intentions go to die. Innosys Asia Technologies runs projects on a simple premise: clients should be able to see progress without asking for it, and scope changes should be priced before they are absorbed.
What you can expect from week one
What follows is how that works in practice, from the first workshop to the release you can actually deploy on a Tuesday afternoon. No black-box phases, no surprise invoices. You see the plan, the board, and the code the same way we do.
The approach is built for business software: websites, mobile apps, and internal digital products where the details decide whether the system is still workable two years from now. It fits teams in Singapore and clients working across time zones, because every decision is written down where you can find it.
Where we work
- Office
- 60 Paya Lebar Road, #06-28, Paya Lebar Square, Singapore 409051
- Hours
- Monday to Friday, 9:00 AM – 6:00 PM
- Talk to us
- 5859730689 · [email protected]
Discovery that produces decisions
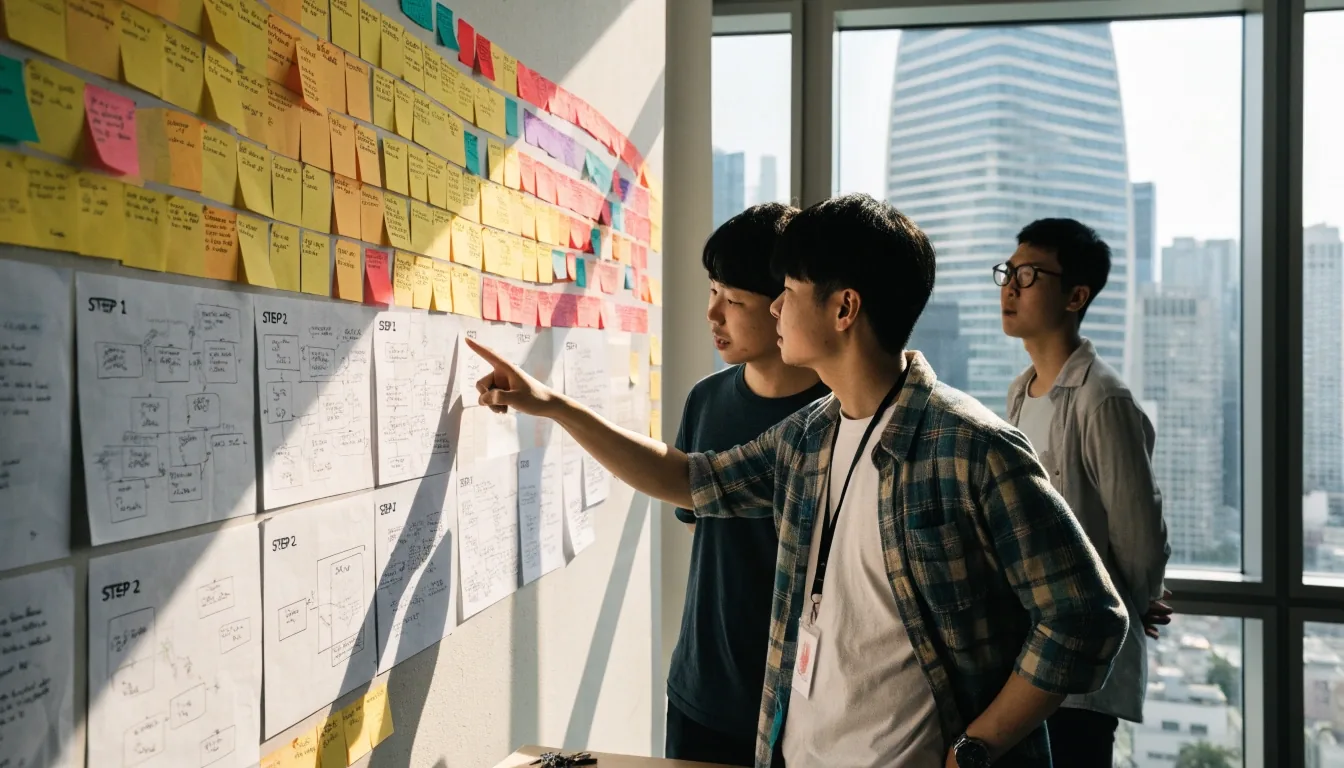
We start with two to three sessions involving the people who will use the system. Not a requirements document exercise. We walk through the current process step by step, including the spreadsheet someone maintains on the side.
The output is a written scope with assumptions listed explicitly, so disagreements surface in week one rather than week ten. If the discovery reveals the project is smaller than you thought, we will say so.
What the sessions leave behind
- A written scope with assumptions stated, not implied.
- A shortlist of the people who will actually use the system.
- Open questions marked as open, so nobody assumes an answer.
- A clear statement when the project turns out smaller than planned.
Planning and estimation
Work gets broken into stories small enough to finish inside a sprint. Estimates come from the engineers who will do the work, not from a salesperson working backwards from your budget.
Ranges, not single numbers
We give ranges and we attach the assumptions behind them. A single confident number for work nobody has done yet is a guess wearing a suit. When an estimate changes because a third-party API behaves differently than documented, you hear about it that week with options attached.
Every story carries the criteria that will prove it is finished. That is what stops a sprint from ending in an argument about whether something is done.
Breaking the work down
Stories are sized so one engineer can finish one inside a two-week cycle, with tests. Large unknowns get a short investigation story before anyone commits to a build.
Who estimates
The engineers who will write the code. Their names sit next to the estimate on the board, so the person answering for the number is the person doing the work.
When things move
Scope changes get priced before they are absorbed. You see the added effort, the schedule effect, and the option to defer it — then you decide.
If a feature is not demonstrable at the end of a cycle, it is not done.
Two-week cycles. A shared board. A demo of working software every time.
Sprint cycles and visibility
Builds run in two-week cycles. The Jira board is shared with you from day one, so sprint contents, blockers, and completed work are visible without a status request. Every cycle ends with a demo of working software.
That last point matters. Demos show running features, not screenshots of progress. If a feature is not demonstrable, it is not done.
Visible from day one
Sprint contents, blockers, and finished work sit on a board you can open whenever you want.
Every cycle closes
A demo of running software, with the acceptance criteria from planning beside it.
Blockers surface early
If something is stuck, it is on the board before it becomes a schedule problem.
Engineering standards
Code lives in version control with review before merge. Environments are containerised with Docker so development, staging, and production behave the same way. Deployments are scripted, repeatable, and reversible.
API work gets documented and tested in Postman before anything depends on it. This is the unglamorous layer that determines whether your system is maintainable in two years or a black box nobody wants to touch.
Review before merge
Every change is read by a second engineer before it joins the main branch. The reviewer checks behaviour and the tests that prove it, not just formatting.
Containerised environments
Docker keeps development, staging, and production on the same footing, so a bug that only appears on one machine stops being a mystery.
Scripted deployments
Release steps are written down and automated, which means a deploy is repeatable and can be reversed if something looks wrong.
Documented APIs
Endpoints are described and tested in Postman before another part of the system relies on them. Integrations stop being guesswork.
Testing and quality
Developers do not sign off their own work. On larger builds a dedicated QA engineer writes and runs test cases against acceptance criteria agreed during planning. On smaller builds, the lead engineer reviews against the same criteria.
Unhappy paths, tested on purpose
We test the unhappy paths deliberately: what happens when a payment fails, when an API times out, when a user submits a form twice. Those scenarios are where production incidents come from.
Who signs off
Not the author. On larger builds a dedicated QA engineer runs the cases; on smaller ones the lead engineer checks the same criteria against the running build.
Test cases come from the acceptance criteria written during planning, so quality is measured against something you already agreed to — not against a feeling at the end of the project.
Launch and handover
Launch is scheduled, not improvised. We deploy to staging first, run through the release checklist, then move to production with a rollback path ready. If a release needs a maintenance window, you will know the date in advance.
Staging first
The release runs on staging before anyone touches production, so the checklist is verified against a real environment.
A rollback path ready
If the release misbehaves, the previous version goes back. You are not waiting for a fix under pressure.
Handover you can use
Documentation, environment access, and a walkthrough for whoever will maintain the system. If that is your internal team, we make sure they can deploy without us.
After launch
Most systems need iteration once real users touch them. We offer support retainers for monitoring, bug fixes, and small enhancements, scoped monthly so costs stay predictable.
Some clients take the code and run it themselves. That is a fine outcome. We would rather hand over something maintainable than create a dependency. What matters is that the system keeps working when our calendar is not part of the picture.
Questions worth asking us
- Can we see the board before signing anything?
- Yes. The board is shared from the first sprint, and you keep access for the length of the project.
- What happens if the estimate is wrong?
- You hear it that week, with the reason and the options attached. Nothing gets absorbed quietly.
- Do you work with existing codebases?
- Often. Discovery starts by reading what exists, and the written scope says what gets kept, replaced, or left alone.
- How is a retainer scoped?
- Monthly, covering monitoring, bug fixes, and small enhancements. The scope is agreed in writing before the month starts.